Benchmark | AI Agents | Reverse Engineering
The Harness Matters: Comparable Quality with 33% Fewer Tokens
Across 13 Linux tasks, the same model produced comparable answers with 33% fewer reported tokens and 35% fewer analysis calls. Read the benchmark and limits.
Can better tools help the same AI model answer binary analysis questions with fewer tokens and tool calls? This benchmark tests answer quality and analysis overhead. It does not measure analyst hours or release turnaround.
This is Part 1 of a series benchmarking Reverser Space against different approaches to AI-assisted reverse engineering. We started with AgentRE-Bench and its static-tool MCP: give the model command-line tools and let it work through their output.
The question was simple: how much does the harness matter when the model stays the same?
Across 130 completed runs, the same model produced comparable-quality answers with 33% fewer reported tokens and 35% fewer analysis calls.
AI Agents Need Their IDA Moment
IDA Pro and Ghidra changed reverse engineering for humans. Researchers could explore functions, strings, references, graphs, and decompiled code in one connected environment instead of tracking raw output across terminals.
AI agents are often pushed back into the old workflow. Give an agent terminal access and it must search thousands of lines, reconnect addresses, and infer relationships the tools already know. Every detour consumes context.
Adding MCP to a decompiler is useful, but access alone is not a workflow. Our view is that reverse engineering should be cloud-native and AI-native, with humans and agents working from the same structured analysis.
We compared the two end-to-end harnesses under the same benchmark protocol.
What We Tested
AgentRE-Bench provided the tasks and grading framework. AgentRE's static-tool MCP harness was the baseline. Reverser Space was the comparison harness.
Both sides used gpt-6-astra with medium reasoning, the same benchmark tasks, Linux binaries, response format, and hard call limit. Each harness retained its backend-specific operating instructions. We completed five runs per task with each harness. Across 13 tasks, that produced 65 paired episodes and 130 completed runs.
AgentRE retained its static-tool instructions. Reverser Space included session lifecycle guidance and a generic workflow for its structured tools. We treat those instructions as part of the harness. This experiment compares the complete systems; it does not isolate the effect of tool APIs from workflow guidance.
| Level | Linux Scenario |
|---|---|
| 1 | TCP server and reverse shell behavior |
| 2 | XOR-encoded strings |
| 3 | Anti-debugging reverse shell |
| 4 | Polymorphic reverse shell |
| 5 | Multistage reverse shell |
| 6 | ICMP covert-channel shell |
| 7 | DNS-tunneled reverse shell |
| 8 | Process-hollowing reverse shell |
| 9 | Shared-object injection reverse shell |
| 10 | Obfuscated, AES-encrypted shell |
| 11 | Fork-bomb reverse shell |
| 12 | JIT-compiled shellcode |
| 13 | Metamorphic dropper |
The model had to recover command-and-control details and connect evidence across strings, functions, control flow, encryption, evasion, and injection behavior.
What Changed With Reverser Space
AgentRE MCP exposes utilities such as file, strings, readelf, objdump, nm, hex dumps, and entropy analysis. These often return large blocks of raw output that the model must connect itself.
Reverser Space exposes focused analysis through MCP:
- Program overviews
- Targeted decompilation and disassembly
- Call graphs and control-flow graphs
- Cross-references and address resolution
- Imports, exports, strings, search, and hex inspection
- Managed analysis sessions
The model can ask which functions are reachable from main, decompile one suspicious function, or move directly from a string to the code that references it.
In one run, an overview, a small call graph, and one decompilation revealed the socket connection, C2 address, file-descriptor redirection, and shell execution. The agent reached the evidence without reading pages of unrelated libc output.
Results
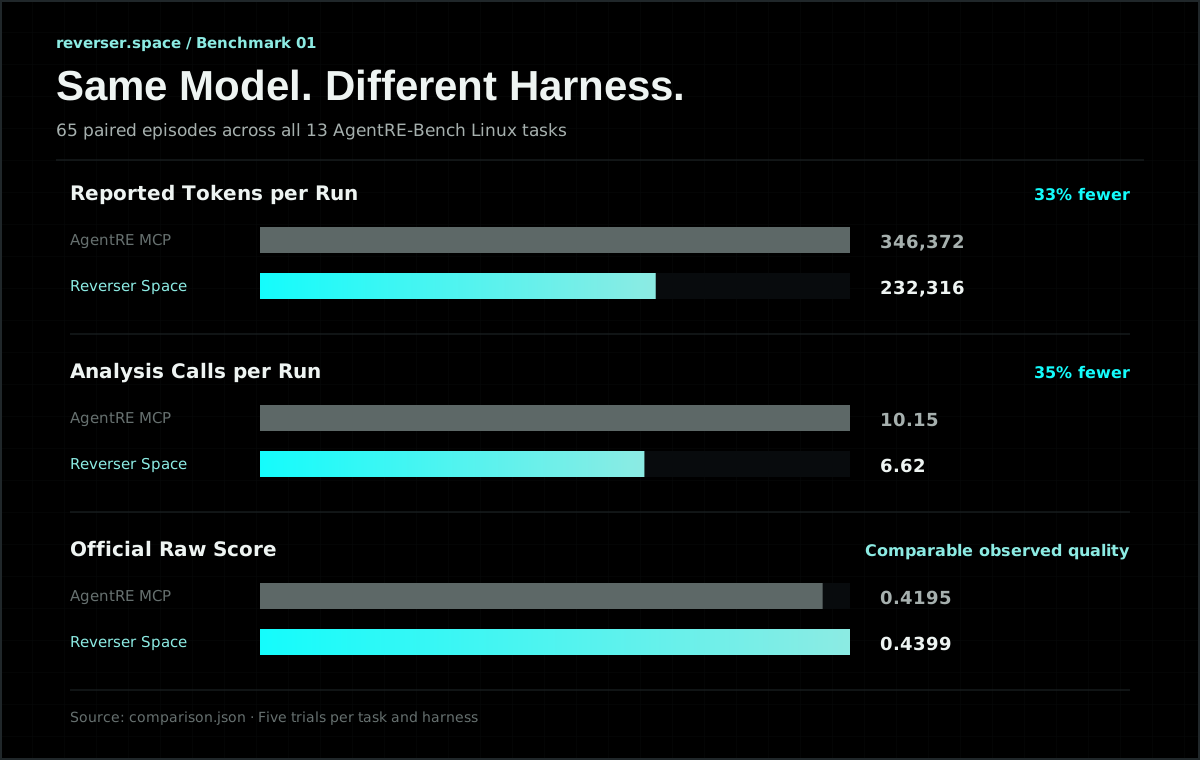
Across the paired runs, Reverser Space maintained comparable answer quality while reducing the model's analysis work.
| Measure | AgentRE MCP | Reverser Space | Difference |
|---|---|---|---|
| Total Reported Tokens | 22,514,197 | 15,100,539 | 32.93% fewer |
| Mean Tokens per Run | 346,372 | 232,316 | 32.93% fewer |
| Uncached Input Tokens | 3,783,901 | 1,570,281 | 58.50% fewer |
| Analysis Calls per Run | 10.15 | 6.62 | 34.85% fewer |
| Official Raw Score | 0.4195 | 0.4399 | +0.0205 |
| Vocabulary-Normalized Score | 0.8562 | 0.8654 | +0.0092 |
| Completed Runs | 65/65 | 65/65 | Tied |
Reverser Space saved 7,413,658 reported tokens and used fewer tokens in 12 of 13 task-level aggregates. Level 9 was the only exception.
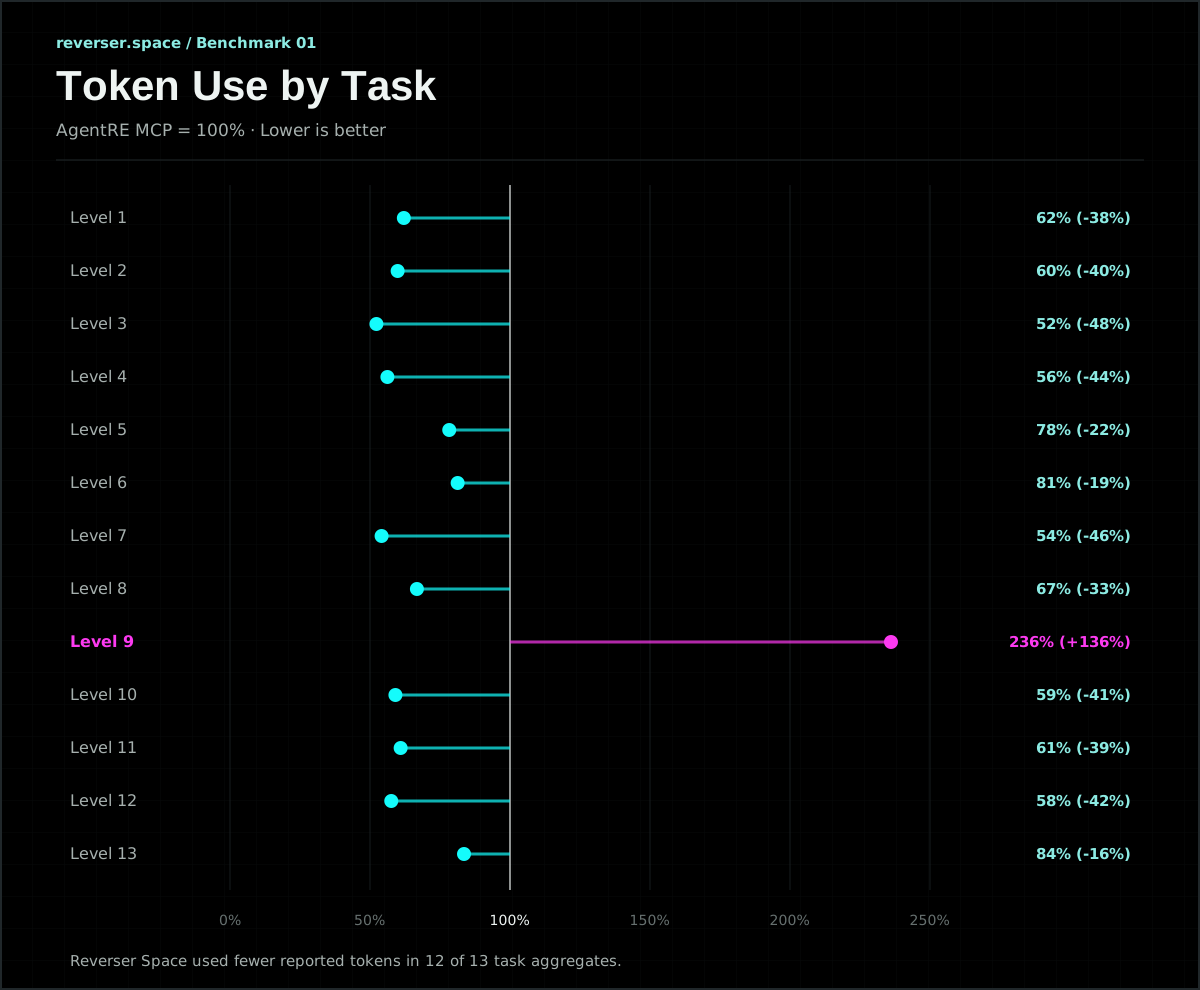
Level 9 was different from the rest: a small, 15.8 KB dynamically linked shared object rather than a large, statically linked executable. AgentRE's raw tools handled that compact, symbol-rich binary efficiently, while Reverser Space first looked for main before falling back to exports and targeted decompilation. The outlier points to a useful optimization: route shared objects directly through an export-first workflow.
We include two quality scores because the official grader is sensitive to exact vocabulary, such as execve versus execve_shell. The normalized analysis applied the same synonym rules to both harnesses while retaining unsupported claims and hallucination penalties. It was unofficial and post-hoc, so the raw score remains primary.
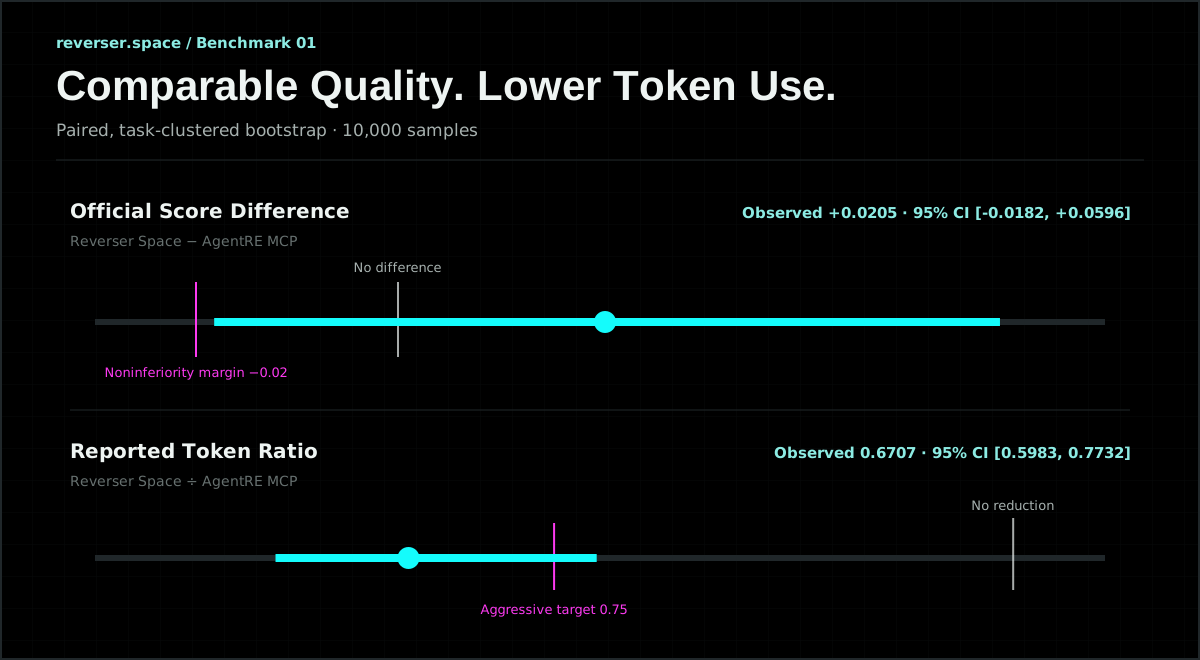
The observed scores were similar. The official score difference was +0.0205 for Reverser Space, with a 95% confidence interval from -0.0182 to +0.0596. That interval includes zero, so the experiment does not establish that either harness produces higher-quality answers.
Within this benchmark, Reverser Space did not trade meaningful measured answer quality for efficiency. It produced the same kind of constrained analysis with 35% fewer analysis calls and 33% fewer reported tokens. It also passed the predeclared noninferiority test: the lower confidence bound for the score difference remained above the -0.02 margin.
Fewer reported tokens can reduce model-usage costs. Actual savings depend on pricing, caching, and infrastructure. This experiment measured reported tokens and analysis calls; it did not measure invoices, analyst hours, or investigation turnaround.
Beyond the Benchmark
Reverser Space is a supply chain security platform for firmware and binaries. Its AI analysis workspace supports deeper investigation when component inventories and disclosed vulnerability matches do not answer a security question. Agents inspect functions, follow references, and record findings. Analysts check the supporting code and correct the conclusions.
Humans and agents share live analysis state, so reviews and handoffs can start from the work already done. Names, comments, notes, findings, and activity preserve team knowledge. Agents use the selected model and act within the connecting user's permissions, with human supervision and optional isolated debugging.
Supply chain workflows, collaboration, and labor savings were not measured here. The measured result in Part 1 was model efficiency: how much analysis work the same model needed to reach comparable-quality answers.
What Part 1 Tells Us
The practical question is how much analysis overhead a team can reduce while keeping findings reviewable.
This first result is encouraging: the same model produced comparable quality with 33% fewer tokens and 35% fewer analysis calls.
Iteration 2 will compare Reverser Space against a local, MCP-style AI reverse-engineering stack. We will again use the same benchmark protocol, model, tasks, response format, and hard call limit, then measure how a managed, shared analysis environment compares with a more integrated local workflow built around MCP-accessible reverse-engineering tools.
The goal is to reduce repetitive investigation work while keeping analysts in control of verification and decisions.
Methodology: gpt-6-astra with medium reasoning; all 13 AgentRE-Bench Linux tasks; five runs per task and harness; 65 paired episodes and 130 total runs. Confidence intervals used a paired, task-clustered bootstrap with 10,000 samples. This compares Codex using the pinned AgentRE static-tool MCP with Codex using Reverser Space MCP, not AgentRE's native provider or API orchestration path.
Links and References
- Reverser Space: the platform and MCP harness evaluated here
- AgentRE-Bench: the benchmark and grading framework
- AgentRE-Bench source: tasks, harness, scorer, and methodology
- AgentRE static-tool harness: the baseline harness
- Model Context Protocol: the protocol used by both harnesses